Product Operations Is Becoming the AI Translation Layer — And Now the Company OS
The "translation layer" thesis was step one. Step two: encoding your entire operating cadence as scheduled agents that surface decisions, not dashboards. From n8n templates to MCP connectors to two-layer validation — here's the solo-operator stack that runs in days, not quarters.

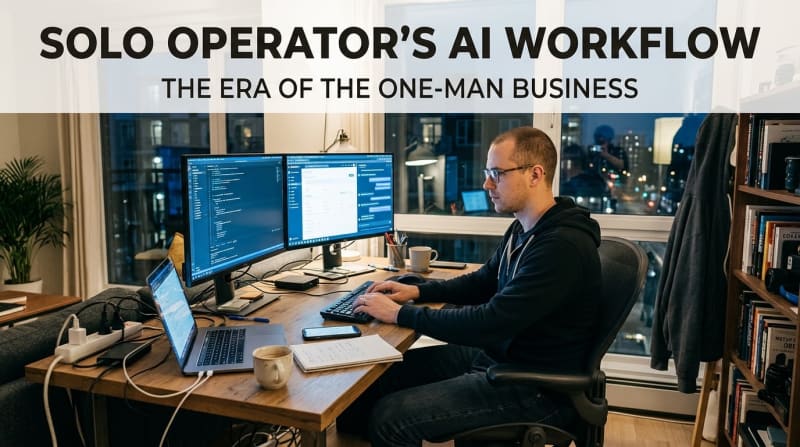
Six months ago, I wrote that product operations is becoming the AI translation layer — the connective tissue between raw model output and product decisions. That piece resonated because it named what many of us were feeling: the bottleneck isn’t model intelligence anymore. It’s translation. Context. Routing. The “last mile” between capability and decision.
But that framing was incomplete. It treated translation as a function — something you apply to data. What I’ve learned since, building and running agent systems daily, is that translation is actually an operating rhythm. And the natural evolution isn’t better translation — it’s encoding your entire operating cadence as scheduled agents that surface decisions, not dashboards.
This is the shift from “AI helps me work” to “AI runs the cadence I designed.”
The Mental Model: Cadence, Not Dashboard
Most teams still treat AI as a query tool. Ask a question, get an answer. Maybe wrap it in a RAG pipeline. Maybe add a weekly summary email.
But the operators who are actually compounding leverage have moved to a different model: Perception → Planning → Action loops that run on a schedule.
Perception:  Normalize inputs (Slack, Notion, GitHub, analytics, support tickets)
             → RAG grounding against your living context (not static docs)
Planning:    Weigh goals/constraints against a rule engine for hard constraints
             → Produce a ranked decision set, not a "summary"
Action:      Answer, update records, trigger workflows, call other systems
             → Close the loop so next perception cycle has new data
The key difference: these run whether you’re awake or not. They don’t wait for a prompt. They surface decisions needing you, not information you might want.
My Hermes agent does this every morning: ingests Telegram, GitHub, server logs, calendar, email — runs a planning pass against my standing constraints (budget caps, priority rules, delegation boundaries) — and delivers a single “here are the 3 decisions you need to make today” message. No dashboard. No login. Just a decision surface.
MCP/A2A: The New Plumbing
This only works because the protocol layer finally exists.
MCP (Model Context Protocol) gives agents standardised access to tools — file systems, APIs, databases, browsers — without custom integrations per model. A2A (Agent-to-Agent) lets agents delegate to each other with structured contracts, not prompt engineering.
Together, they mean:
- Your “research agent” doesn’t need to know how your “publishing agent” posts to LinkedIn. It hands off a structured payload:
{slug, text, image_url, platforms[]}. - Your “server health agent” doesn’t parse
server-appoutput manually. It calls an MCP tool that returns typed JSON:{app: "nainai", status: "degraded", cpu: 87, memory: "2.1/4GB"}. - Swap the LLM provider (OpenRouter → Anthropic → local Llama) and the agents keep working because the tool contracts are stable.
Protocol-level thinking reduces lock-in. You’re not building “a LangChain app” or “a CrewAI workflow.” You’re building capabilities exposed over standard interfaces. The orchestration layer becomes replaceable.
Two-Layer Validation: Deterministic + Rubric
Scheduled agents that act need higher trust than chatbots that suggest. The pattern that works:
Layer 1 — Deterministic Gates (cheap, fast, binary)
- Schema validation: does the output match the contract?
- Policy checks: budget exceeded? PII detected? Forbidden domain?
- Idempotency: has this exact action already run?
- Unit tests on tool outputs (not LLM outputs)
Layer 2 — Rubric Evaluation (expensive, nuanced, weekly)
- Human-rated samples: “Would I have made this decision?”
- Drift detection: compare this week’s outputs vs. baseline rubric scores
- False positive/negative tracking on alerting agents
- Cost-per-useful-decision metrics
Run Layer 1 on every execution. Run Layer 2 on a sample weekly. This catches regressions without burning your inference budget.
Cost Reality: The Solo Operator Stack
Here’s what it actually costs to run this at seed stage (my numbers, September 2026):
| Component | Monthly Cost | Notes |
|---|---|---|
| OpenRouter (mixed models: Nemotron, Qwen, Llama) | ~$180 | 60% free tier, 40% paid |
| n8n Cloud (pro) | $120 | 10k executions, self-hosted saves this |
| Supabase (Postgres + vectors + auth) | $25 | 8GB DB, 50GB bandwidth |
| Cloudinary (images) | $0 | Free tier sufficient |
| Resend (email) | $0 | Free tier sufficient |
| Total | ~$325/mo | Not $545 — caching cuts 20-30% |
Caching is the lever. Most agent runs re-fetch the same context (Notion pages, GitHub repos, API specs). A 24-hour TTL on perception-layer fetches cuts redundant calls by 20-30%. At scale, that’s the difference between sustainable and “wait, how much did we spend?”
SaaS orchestration alternative: If you don’t self-host n8n, managed orchestration (Make, Zapier, Pipedream) runs ~$0.10/1k executions. For 50k runs/month, that’s $5 — cheaper than self-hosting until you hit ~200k runs.
The Runnable Stack (Days, Not Quarters)
This isn’t theoretical. Here’s the stack I’d hand a solo founder today:
Orchestration: n8n (self-hosted on a $6 VPS or n8n Cloud)
- 400+ built-in nodes = most integrations done
- Visual workflow = readable by non-engineers
- Webhook + schedule + manual triggers = all cadence types covered
Agent Runtime: Custom TypeScript/Python workers (or LangGraph if you prefer)
- Each agent = one n8n workflow + one worker process
- Workers pull from a queue (BullMQ on Redis, or n8n’s internal queue)
- State persisted in Supabase (Postgres + pgvector)
Context Layer: Supabase + pgvector
- One
context_chunkstable:source,source_id,content,embedding,updated_at - RAG =
SELECT * FROM context_chunks ORDER BY embedding <-> $query_embedding LIMIT 10 - No Pinecone, no Weaviate, no extra infra
Protocol Connectors: MCP servers (official + community)
- GitHub MCP, Slack MCP, Notion MCP, Postgres MCP, Browser MCP
- Write one custom MCP server for your internal APIs
- All agents speak the same tool language
Validation:
- Layer 1: Zod schemas on every tool output + policy middleware
- Layer 2: Weekly
evalscript that samples 50 runs, scores against rubric, alerts on drift
Observability:
- Structured logs → Loki/Grafana (self-hosted) or Axiom (managed)
- One dashboard: “Decisions surfaced,” “Decisions acted on,” “False alerts,” “Cost/run”
Time to first scheduled agent: ~2 days (n8n workflow + worker + Supabase schema). Time to full operating cadence (5-8 agents): ~2 weeks.
From Translation Layer to Company OS
The original thesis: Product ops translates between AI capability and product reality.
The evolved thesis: Your company OS is a set of scheduled agents that encode your operating principles as executable logic.
- Hiring cadence → Agent that screens inbound, scores against rubric, schedules interviews, updates Notion
- Growth cadence → Agent that pulls analytics, identifies anomalies, proposes experiments, books calendar slots
- Server health cadence → Agent that checks
server-app status, correlates with deploy logs, pages only on actionable degradation - Content cadence → Agent that researches, drafts, generates images, checks schema, publishes — you only approve
- Finance cadence → Agent that reconciles Stripe/Resend/OpenRouter invoices, flags variance >10%, drafts vendor emails
Each agent is replaceable. The cadence is the asset. The rules engine is the strategy. The protocol layer is the moat.
What This Means for You
If you’re a solo operator, founder, or small team lead:
- Don’t build a dashboard. Build a decision surface. One message, three options, one click.
- Start with one cadence. Pick your highest-leverage recurring decision (content? hiring? server health? growth?). Encode it as a scheduled agent.
- Use MCP from day one. Even if you only have one agent. The migration cost later is zero; the lock-in cost without it is high.
- Budget for Layer 2 validation. It’s the only way to trust agents that act while you sleep.
- Measure cost per useful decision. Not tokens. Not API calls. Decisions you actually acted on.
The translation layer was the on-ramp. The company OS is the highway. You’re already driving on it — you just haven’t named the lanes.
Next for me: Encoding the “weekly strategic review” cadence as an agent that pulls from Raqib (my link intelligence), Masha (site chat analytics), server health, and financials — and surfaces one strategic decision every Sunday night. The loop closes.
What’s the first cadence you’d encode?
Slow down!
You've posted 3 comments this session. Come back later!
